


WordPress’s default search matches keywords against a database column — if a visitor’s words don’t literally appear in the post, it doesn’t show up, even when the post directly answers their question. Vector search fixes that specific gap by matching meaning instead of exact words.
Why Keyword Search Misses So Much
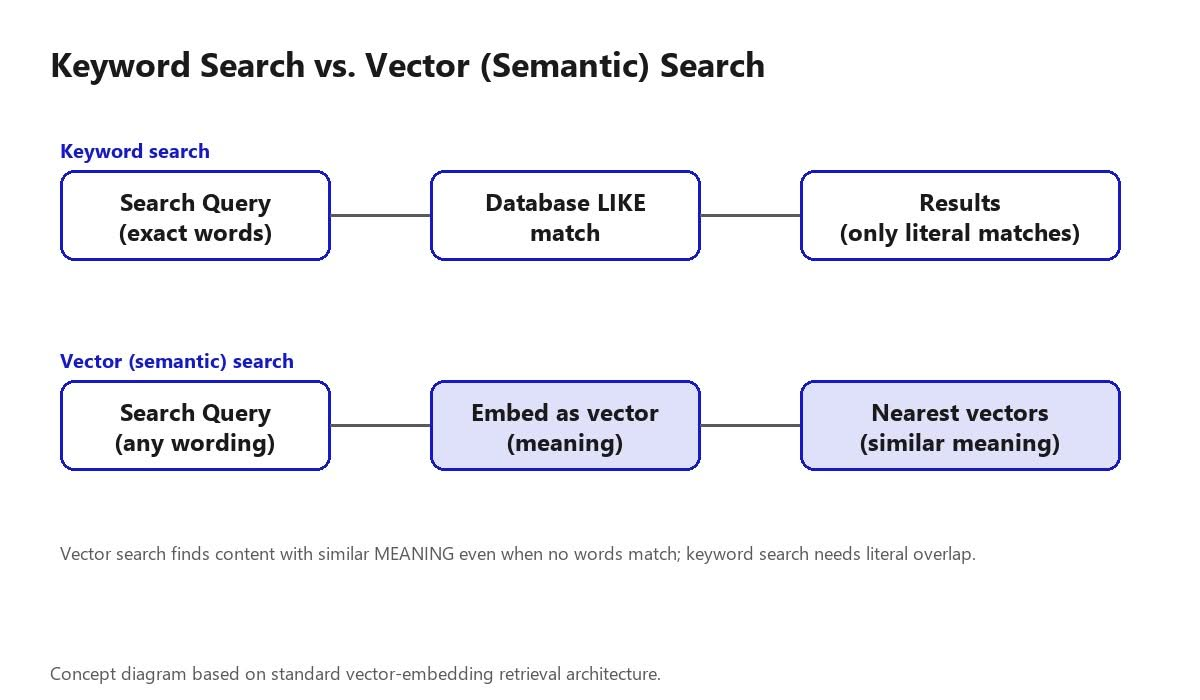
WordPress’s built-in search runs a LIKE query against post titles and content. A visitor searching how do I make my site faster won’t find a post titled Core Web Vitals Optimization Guide unless those exact words happen to also appear in the body — the search engine has no concept that the two phrases mean roughly the same thing.
Also Read: Best WordPress Search Plugins Compared — several of the plugins compared there now include semantic/AI search as a feature, distinct from this post’s focus on the underlying mechanism.
How Vector (Semantic) Search Actually Works
- An embedding model converts each piece of content (and later, each search query) into a vector — a list of numbers, typically hundreds to low thousands of dimensions, representing its meaning in a high-dimensional space.
- Content with similar meaning ends up with vectors that are mathematically close to each other, regardless of whether they share any actual words.
- A search query gets converted into its own vector at search time, and the system finds the stored content vectors closest to it — this is the actual search step, typically using a specialized vector database or a vector-search extension.
- Results are ranked by that closeness (a similarity score, most commonly cosine similarity — the angle between two vectors rather than the raw distance between them), not by keyword-match frequency.
The Chunking Step Most Explanations Skip
A single vector can’t meaningfully represent an entire long blog post — cramming a 2,000-word article into one embedding averages away most of its specific detail, so a query about one paragraph deep in the piece may not register as close to that single, blurred-together vector. Real implementations split long content into smaller chunks (a few paragraphs, or a fixed token window) before embedding each chunk separately, then search returns and ranks individual chunks rather than whole posts. This is also why chunk boundaries matter: cutting a chunk mid-thought, severing a heading from the paragraph it introduces, tends to produce worse retrieval than splitting at natural section breaks, since each chunk needs to make sense as a self-contained unit of meaning on its own.
What This Requires on a WordPress Site
- An embedding step that runs (usually via an API call to an embedding model) whenever content is published or updated.
- Somewhere to store the resulting vectors — a dedicated vector database, or a vector extension on top of an existing database.
- A query-time embedding + similarity search step replacing (or supplementing) the default WordPress search query.
Most site owners won’t build this from scratch; it typically arrives as a feature inside a search plugin or an AI-search add-on, with the embedding and vector-storage machinery handled behind the scenes.
Also Read: Nexter Abilities Explained: The WordPress Abilities API Inside Nexter Blocks — a related but distinct AI-connectivity layer, for agent actions rather than search relevance.
Why WordPress’s Own Database Isn’t Built for This
WordPress runs on MySQL by default, which has no native vector column type or similarity-search capability — this is the core technical reason vector search always arrives as an add-on rather than a core WordPress feature. The comparable capability in the Postgres world is pgvector, an extension that adds a vector data type plus specialized indexes directly inside PostgreSQL, letting an application run semantic search without standing up an entirely separate vector database. A WordPress search plugin implementing vector search either talks to an external, purpose-built vector database over an API, or (less commonly, and usually on a more customized WordPress-on-Postgres setup) relies on something like pgvector directly. Either way, the vectors themselves don’t live in WordPress’s normal wp_posts table — there’s always a separate storage and query layer involved.
Why Real Vector Search Doesn’t Check Every Vector: Approximate Nearest Neighbor
Comparing a query vector against every single stored content vector, one by one, would be accurate but far too slow at any real scale — a site with tens of thousands of chunks would mean tens of thousands of comparisons per search. Production vector search instead uses an approximate nearest neighbor (ANN) algorithm, most commonly an index structure called HNSW (Hierarchical Navigable Small World), which organizes vectors into a multi-layered graph that lets a search jump toward the closest matches without touching most of the dataset. The tradeoff in the name is real: results are approximate, not guaranteed to be the mathematically exact closest match, in exchange for search that stays fast as the content library grows. For the overwhelming majority of on-site search use cases this tradeoff is invisible to a visitor, since the approximate top results and the exact top results are effectively the same in practice.
Vector Search’s Own Blind Spot: Why Hybrid Search Exists
Vector search isn’t a strict upgrade over keyword search — it trades one blind spot for another. It’s excellent at matching intent and paraphrase, but weaker on exact, literal matches: a visitor searching a specific error code, a model number, or an exact product SKU is often better served by a plain keyword match than by semantic similarity, which can surface conceptually related but literally wrong results for that kind of query. This is why most production search systems that adopt vector search run it as hybrid search — combining a keyword match score and a vector similarity score for the same query, rather than replacing one with the other outright.
What to Actually Check Before Adopting It
- Does the plugin run hybrid search, or pure vector search? Pure vector-only implementations tend to underperform on exact-match queries like SKUs or model numbers.
- Where does re-embedding happen on content updates? A stored vector reflects the content at the time it was generated; check whether an edited post automatically triggers a fresh embedding, or whether search results can silently go stale against edited content.
- What’s the ongoing cost? Embedding generation is typically billed per API call by the embedding provider; a large site with frequent content updates has an ongoing, usage-based cost here, not just a one-time setup cost.
- How does it chunk long content? Ask (or check the docs) whether long posts get split into multiple embedded chunks rather than one blurred whole-post vector; this materially affects result quality on longer articles.
Conclusion
Vector search doesn’t replace keyword search outright so much as catch what it structurally can’t: queries that mean the same thing as your content but don’t share its exact words. For a large site with real on-site search volume, that gap is often the difference between a visitor finding the right page in one search and bouncing after a zero-result query — but check for a hybrid implementation and sensible chunking, since pure vector search trades away exact-match reliability it’s easy not to notice until an SKU search fails.
FAQ
Does WordPress support vector search natively?
Not out of the box. WordPress’s default MySQL database has no native vector type, so it requires a plugin or add-on that handles the embedding generation and vector storage/query layer separately.
Is vector search the same thing as AI search?
Vector search is one common mechanism behind AI-powered or semantic search features; the terms overlap significantly but vector search specifically refers to this meaning-based matching technique.
Is this related to how ChatGPT or Google’s AI Overviews find my content?
The same underlying vector-embedding concept is used broadly across AI retrieval systems, though the specific implementation an AI search engine uses to find and cite your content is separate from your own site’s internal search feature.
Why did a vector search return conceptually related but wrong results for an exact product code?
Pure vector search is weaker on exact, literal matches like SKUs or model numbers, since it ranks by semantic closeness rather than literal string matching. This is exactly the gap hybrid search (vector + keyword combined) is built to close.
Why do vector search results say “approximate” instead of exact?
Comparing a query against every stored vector one-by-one would be too slow at real scale, so production systems use an approximate nearest neighbor index like HNSW that trades a small amount of accuracy for search speed that stays fast as content grows. In practice the approximate and exact top results are nearly always the same.
Suggested Reading
- Best WordPress Search Plugins Compared
- Nexter Abilities Explained: The WordPress Abilities API Inside Nexter Blocks
- OpenAI’s Apps SDK and the New ChatGPT App Store: Should Your Business Build One?
